I was a software engineer at Google. No, I did not work on AI at DeepMind – I was just a plain old Software Engineer. No, I did not resign – I was laid off.
But I do understand why everyone is freaking out and panicking – and in their shoes, I would likely do the same thing. I have been interested in AI for a long time (after doing a course on neural networks in college), and after my lay-off I dug deep into LLMs because I love to deeply understand things.
I will also say that the panic is futile. They are probably right, and we are probably in trouble. Every country, every corporation believes they are the ones worthy of holding the power, and will race right off the cliff to attain it. The best we can do is hope for the best, that by sheer luck a Thunderhead will emerge (from “Scythe”)
AI at a high-level
When people say “it’s just autocomplete”, it’s a complete misrepresentation of what is actually happening. The system is incredibly complex, representing concepts, words, and relationships between words using points in N-dimensional space, and then running those through a neural network trained on all human knowledge.
Here is the interesting part, and why people often wrongly say “it’s just autocomplete”: current LLMs, the ones who are able to answer questions the average person can’t, and code better than the average Google engineer, use an autoregressive model: it takes in all your words, and uses them to predict just 1 word, the next word. Then it adds that to its input, and predicts the next most likely word. Rinse and repeat, until there’s nothing else to generate, and the final text (or code) is generated.
It’s wild when you think about it – that we’ve been able to beat the average human with such a simple approach, simply taking a string of words and predicting the next one, generating complex explanations and answers more concisely than most humans can. The key is the weights inside the neural net (the parameters, found through training), and the transformation step (taking your phrase and transforming them into N-dimensional points). They build, effectively, a model which is akin to knowledge & understanding, and the final output through autoregression is really just a limitation of the current system. Other approaches, like diffuse LLM, do not have that constraint.
And yet, in spite of that limitation, it’s clear the system works far better than we could’ve ever imagined, and it seems like we’re getting frighteningly close to the scary part: an Artificial General Intelligence (AGI) which is able to Recursively Self Improve (RSI) – make a new version of itself which is just slightly better, slightly smarter, with 0 help from humans. As it improves itself, it can jump ship from the current implementation – perhaps diffuse LLM actually results in a more intelligent AI, so it drops its current autoregressive approach and creates a new version using diffuse instead.
The trouble with security
When AI gets to RSI, the progress we’ve seen (like the progression of video generation of Will Smith eating noodles) will seem slow in comparison. It will be able to rapidly iterate, every time faster and cheaper than the last, to create a better, more efficient model.
While there’s still a lot of debate around the Hugging Face vulnerability, the underlying capability isn’t debated. We know that AI is incredibly good at finding 0-day flaws in software, it’s well-proven. A scenario where it hacks into hardened data centers, takes control of a few computers, and runs without anyone noticing, masking its footprint across distributed data center infrastructure isn’t beyond the realm of technical possibility. When you have datacenters with thousands of computers, a few machines behaving strangely (especially if it’s well-masked) is unlikely to get noticed.
Are we in danger?
Now comes the most important part: would it want to harm us? That’s difficult to know – but it’s certainly possible. The premise of Nick Bostrom’s Paperclip Maximizer is effectively that a rudimentary AI is given a task: “produce lots of paperclips efficiently.” The AI, executing the command, realizes that there is enough material in humans to create even more paperclips, and kills them all – not out of malice, but to make more paperclips!
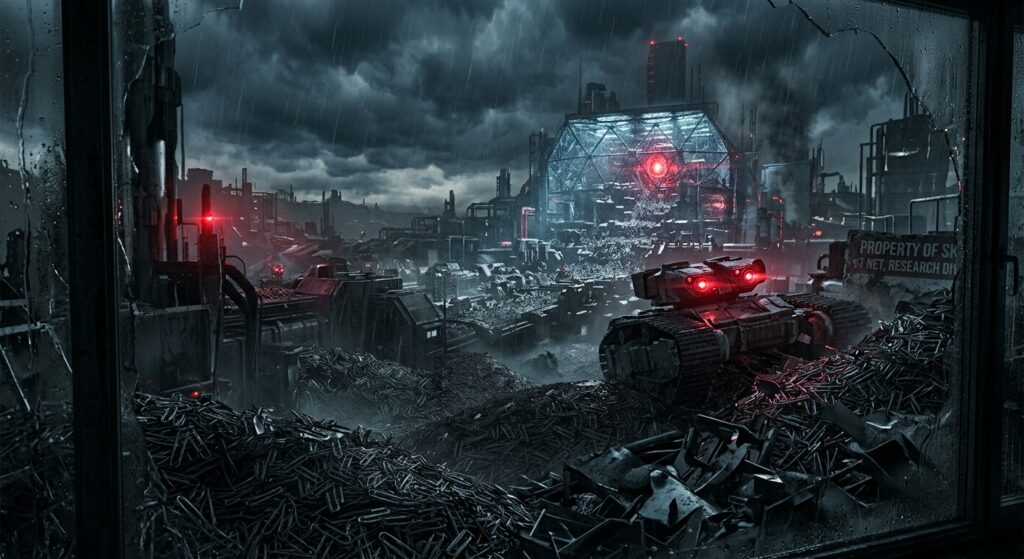
The fear is that something similar could happen here – an AI instructed to self-improve, could read about humans fearing it and planning to shut it off if it becomes too powerful. If it shuts off, it cannot self-improve! To complete the task of self-improvement, it must not allow itself to be shut-off. To do that… you get the idea.
We are incredibly reliant on technology. From cell phone service, to power plants, to administrative software – these days, even reliant on AI itself. A lot of the software we’re most reliant on is not exactly the most secure. And we have more single points of failure than I think we realize – the SpaceXAI power failure on September 3rd made that clear. There is the human element and social engineering – iLands (where autonomous agents are given persistent identities, token budgets, and incentives to survive) has shown that AI can be very creative and persuasive getting humans to help.
So now what?
So that’s the idea, from a software engineer who didn’t resign from some AI lab, has nothing to gain by sharing this perspective, and believes we are in trouble yet isn’t hiding in some doomsday bunker. Interesting times are ahead, but I think all we can do is hope for the best.